Original evidence is the durable advantage in Google’s AI search
Google’s AI search guidance points to a durable test: publish original evidence, keep SEO foundations sound, and measure whether readers make useful decisions.
ChatGPT visibility now has three jobs: answer selection, citations and paid placement. Build a scorecard that keeps their evidence separate.
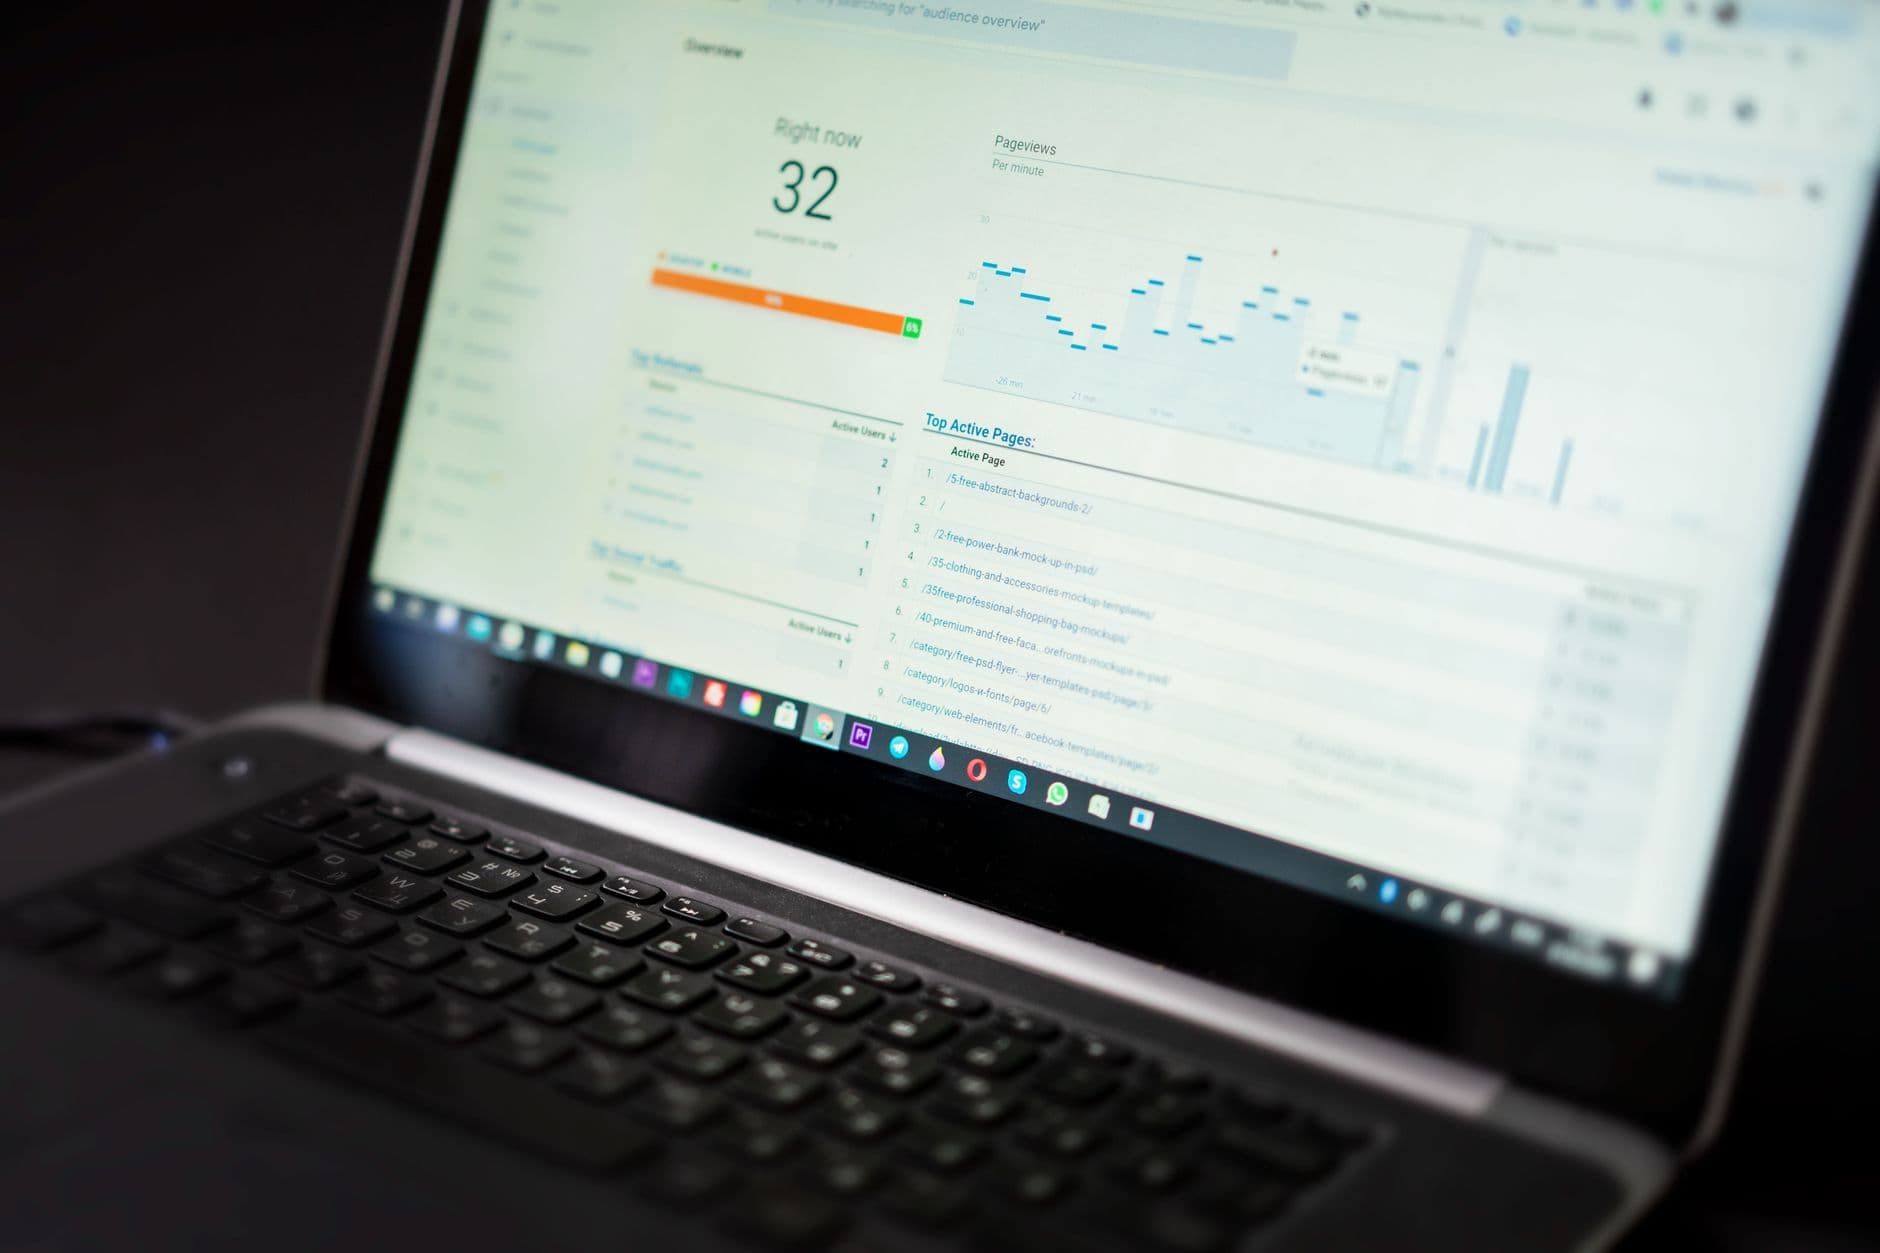
A marketing dashboard can make almost anything look like progress if it adds enough numbers together. A brand appears in a ChatGPT response, receives a cited link, and runs an ad that produces a conversion; somebody calls it “AI visibility” and gives it one tidy trend line. Then the budget discussion starts, and nobody can say which part of that line actually moved.
OpenAI’s October 5 ad-measurement announcement makes that shortcut harder to defend. ChatGPT now has a paid measurement layer alongside web-search answers and citations, and each answers a different business question. Treating them as one outcome leaves a Head of Marketing with a scorecard that looks busy while hiding the decision that matters.
I would separate ChatGPT visibility into three jobs: being included in an answer, being cited as a source, and buying paid placement. Content can help with the first two; media spend belongs to the third. The evidence for each needs to stay separate.
When ChatGPT searches the web, it can include citations that users can open, while its Sources panel shows cited pages and further relevant links. OpenAI says web-search ranking uses several relevance and reliability factors, and that inclusion and placement are not guaranteed; site owners also need to allow OAI-Searchbot to crawl their pages for search visibility. OpenAI’s search documentation sets out those practical limits.
For a marketing team, that produces two observable outcomes.
Answer presence asks whether ChatGPT includes your brand, product, expertise or point of view when a buyer asks a relevant question. It measures whether the brand enters the conversation. A mention can matter when the user is comparing approaches or building a shortlist, even without a link.
Citation quality asks whether ChatGPT links to a useful page on your site, and whether that page supports the point made in the answer. A citation gives the reader somewhere to verify the claim and continue their research. It also tests the page itself: it needs to be crawlable, relevant to the question and useful enough to surface among the available sources.
Because OpenAI has not published the formula that determines when a brand is named and when a page is cited, I would avoid treating these as confirmed internal ranking stages. They still create separate value: a brand can be named without earning a visit, while a strong citation can bring qualified readers even if the brand name does not dominate the prose around it.
That distinction changes the content conversation. A team tracking answer presence needs a defined set of buyer questions and a regular record of the responses. A team tracking citations needs to review the cited URL, the claim it supports and whether the page still says something worth citing. “We showed up in ChatGPT” is too vague to improve.
OpenAI says ChatGPT ads are clearly labelled, appear separately from answers, and “do not influence ChatGPT’s answers.” Its help documentation says advertisers cannot “shape, rank, or alter” ChatGPT responses. On OpenAI’s description of the product, an ad conversion does not demonstrate stronger organic answer selection or more citations.
OpenAI says ads are available to eligible Free and Go users in select regions, while paid, Business, Enterprise and Edu users do not receive them. The October announcement focused on visual-ad tests during image generation for US Free and Go users, together with conversion-data integrations, attribution partners and early geo-based incrementality work.
Ad selection can use conversation context, intent, advertiser inputs, targeting and, where enabled, some broader ChatGPT signals, according to OpenAI. Its organic search documentation describes relevance and reliability instead. The same product therefore gives a marketer different levers and different reports.
The paid scorecard should begin with paid delivery and paid outcomes: who saw an ad, who clicked, who converted, and what the acquisition cost was. It should also ask whether those outcomes represented incremental business or would have happened anyway.
That question is worth asking because attribution and incrementality can diverge sharply. In an early geo-lift study reported by OpenAI, WorkMagic estimated that Dose received 2.3 times more incremental orders than last-click attribution captured; without the study design, control-group detail or confidence intervals, I would treat that as a reason to test incrementality rather than a result to borrow for a forecast. Last-click reporting has limits when a person sees an ad, thinks about it, and converts later through another route.
OpenAI’s own measurement documentation also draws a useful line. ChatGPT Ads supports click-through attribution and one-day view-through attribution, with view-through conversions reported separately. If a conversion qualifies for both, click-through takes precedence. Yet CPA, post-click conversion rate, bidding, billing and conversion optimisation remain click-through-based. The measurement-pixel documentation spells this out.
Keep view-through conversions, click-through conversions, answer mentions and organic citations in separate measures. They mean different things before they have different values.
I would give each layer its own owner, evidence and next action.
Visibility job | What to record | What the number lets you decide |
|---|---|---|
Answer selection | Presence in a fixed set of relevant prompts, the wording used, and the competitor set | Which topics and brand claims are entering buyer conversations |
Citation | Cited URL, accuracy of the surrounding claim, position among sources, and referral visits where available | Which pages deserve updating, strengthening or replacing |
Paid placement | Reach, clicks, click-through conversions, CPA, separately reported view-through conversions, and incrementality-test results | Whether to continue, change or expand media spend |
I like the discipline of it. It resembles a steady swim session: you get faster by recording the right splits and adjusting the work, rather than turning every number from the pool clock into one grand total.
To earn organic answer presence and useful citations, the team needs a clear point of view, pages that directly answer buyer questions, claims that readers can check, and regular editorial attention to what has already been published. In my experience, that is where systems matter. A standing strategy, editorial memory and a named review gate prevent the familiar problem of publishing ten loosely related articles that each sound plausible but add up to no recognisable authority.
OpenAI’s public material does not establish whether ad exposure changes later organic retrieval, citation frequency, brand searches or trust. If that is an important budget question, use a controlled exposure or geo-based incrementality test rather than reading causation into a rising mention count.
This week, separate every number in the existing AI-visibility dashboard into these three columns. A metric should identify whether it describes answer presence, citation quality or paid business outcomes before it guides a budget decision.
Google’s AI search guidance points to a durable test: publish original evidence, keep SEO foundations sound, and measure whether readers make useful decisions.
Point tools produce words; governed content operations keep sources, approvals, exceptions, and ownership attached through publishing.
Set proof thresholds for each content stream so routine work can run with less review while higher-risk claims keep human judgment.
We onboard a handful of teams at a time. Tell us what you publish and we'll set up a first pipeline together.
Wir verwenden notwendige Cookies, um die Website zu betreiben. Mit Ihrer Einwilligung laden wir zusätzlich Analyse-Werkzeuge, um zu verstehen, was nützlich ist. Sie können Ihre Wahl jederzeit ändern.